Free Online Qwen3-TTS Powerful AI Voice Generation
No Login Required • No Credit Card • Start Instantly
97ms Ultra-Low Latency | Voice Cloning | 40+ Voices | 10 Languages | Alibaba AI
0 / 1000 characters
What is Qwen3-TTS
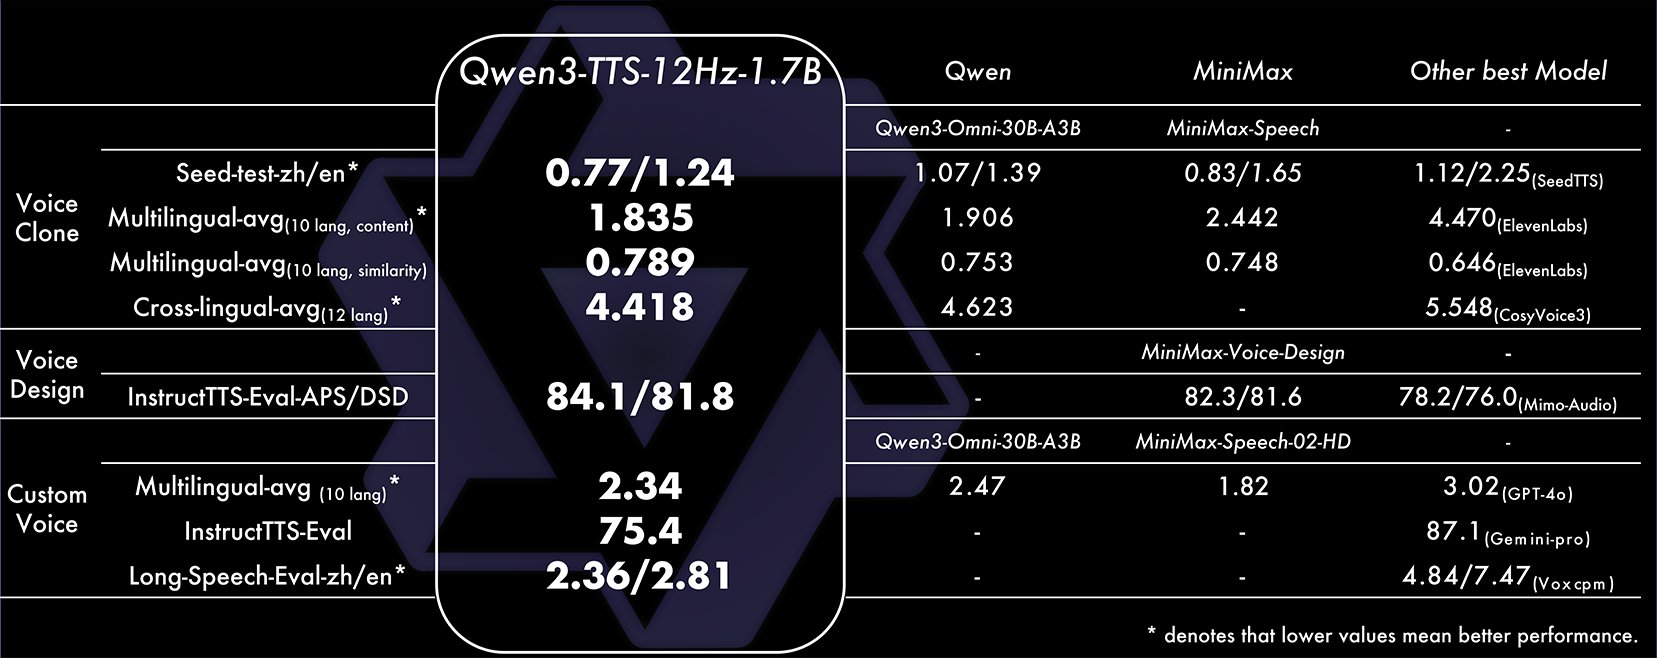
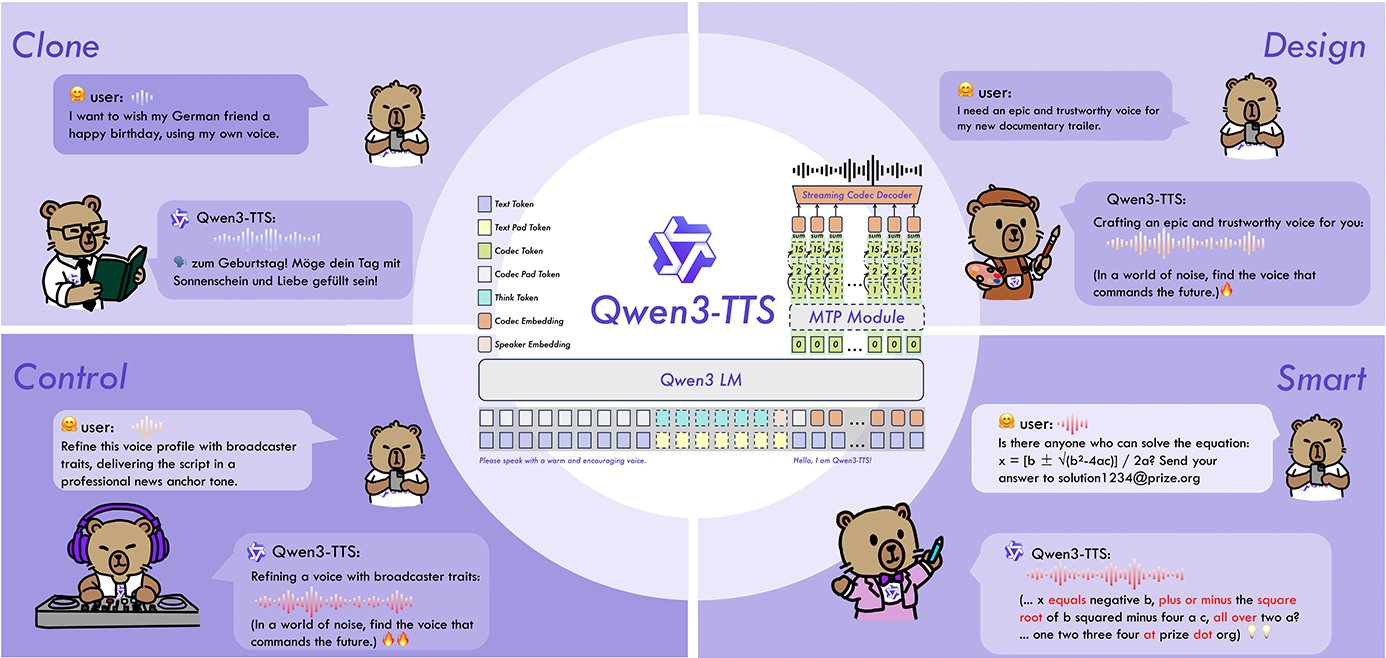
Qwen3-TTS is an open-source series of TTS models developed by the Qwen team at Alibaba Cloud, supporting stable, expressive, and streaming speech generation, free-form voice design, and vivid voice cloning.
- Ultra-Low Latency StreamingOutput the first audio packet immediately after a single character input, with end-to-end synthesis latency as low as 97ms.
- Voice Clone & Design3-second rapid voice clone from user audio input, plus free-form voice design based on natural language descriptions.
- Multi-Language SupportCovers 10 major languages: Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian.
Why Choose Qwen3-TTS
Experience the most comprehensive set of speech generation features available, from voice cloning to intelligent voice control.
How to Get Started with Qwen3-TTS
Start generating high-quality speech in four simple steps:

Key Features of Qwen3-TTS
Comprehensive speech generation capabilities for developers and users.
Voice Cloning
Clone any voice with just 3 seconds of audio. Fast, accurate voice replication for various applications.
Voice Design
Create custom voices using natural language descriptions. Design unique voice characteristics with simple instructions.
Streaming Generation
Ultra-low latency streaming with 97ms end-to-end synthesis. Output first audio packet immediately after single character input.
Multi-Language Support
Support 10 major languages: Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian.
Natural Language Control
Intelligent text understanding with adaptive control over tone, speaking rate, and emotional expression based on instructions.
Open Source
Fully open-source with Apache-2.0 license. Available on GitHub, Hugging Face, and ModelScope for free commercial use.
Qwen3-TTS Performance
Industry-leading metrics for speech generation quality and speed.
End-to-End Latency
97ms
Ultra-Low Latency
Languages Supported
10
Major Languages
Voice Clone Time
3s
Fast Cloning
What Users Say About Qwen3-TTS
Hear from developers and researchers who are using Qwen3-TTS for their speech generation projects.
Alex Chen
AI Researcher
Qwen3-TTS's 97ms latency is incredible! We integrated it into our real-time voice assistant and the streaming generation works flawlessly. The voice cloning quality is outstanding.
Sarah Kim
Developer at VoiceTech
The voice design feature is a game-changer. We can create custom voices for different characters using simple natural language descriptions. It's so intuitive and powerful.
Michael Thompson
Content Creator
As a content creator, Qwen3-TTS gives me everything I need - voice cloning, multi-language support, and expressive speech generation. The 3-second clone time is amazing!
Emma Garcia
Product Manager
We integrated Qwen3-TTS into our audiobook platform. The multi-language support and natural language control make it perfect for our global audience. Quality is production-ready!
David Wilson
Tech Lead
Qwen3-TTS's open-source nature and comprehensive documentation made integration seamless. The vLLM-Omni support and DashScope API options give us flexibility for deployment.
Lisa Zhang
Startup Founder
From prototype to production in days! Qwen3-TTS's voice cloning and design capabilities enabled us to build a personalized voice assistant quickly. The open-source license is perfect for our startup.
Frequently Asked Questions About Qwen3-TTS
Have another question? Visit GitHub Issues or Hugging Face Discussions.
What is Qwen3-TTS and what makes it different?
Qwen3-TTS is an open-source series of TTS models developed by the Qwen team at Alibaba Cloud. It supports stable, expressive, and streaming speech generation, free-form voice design, and vivid voice cloning. Key differentiators include ultra-low latency (97ms), natural language-based voice control, and comprehensive multi-language support across 10 major languages.
What hardware do I need to run Qwen3-TTS?
Qwen3-TTS models require GPU support. We recommend using FlashAttention 2 to reduce GPU memory usage. Models can be loaded in torch.float16 or torch.bfloat16. For optimal performance, use a GPU with sufficient VRAM (8GB+ recommended). The models are also available via DashScope API for cloud-based inference without local hardware requirements.
What are the different Qwen3-TTS models and which should I use?
Qwen3-TTS offers several models: CustomVoice (9 premium timbres), VoiceDesign (create voices from descriptions), and Base (voice cloning). Choose CustomVoice for predefined voices, VoiceDesign for custom voice creation, or Base for cloning existing voices. All models support streaming generation and 10 major languages.
How fast is Qwen3-TTS and can it do real-time generation?
Qwen3-TTS achieves end-to-end synthesis latency as low as 97ms, making it suitable for real-time interactive scenarios. It supports streaming generation where the first audio packet can be output immediately after a single character is input, using the innovative Dual-Track hybrid streaming generation architecture.
Can I use Qwen3-TTS commercially?
Yes! Qwen3-TTS is fully open-source under the Apache-2.0 license, which allows free commercial use. You can deploy, modify, and integrate it into your commercial projects without any additional licensing fees. Models are available on GitHub, Hugging Face, and ModelScope.
How do I get started with Qwen3-TTS?
The easiest way is to install the qwen-tts Python package from PyPI. Create a clean Python 3.12 environment, install the package, and load any released model. You can also try the online demos on Hugging Face or ModelScope, or use the DashScope API for cloud-based inference. Check the GitHub repository for detailed documentation and examples.
Start Using Qwen3-TTS Today
Try free online. Experience 97ms ultra-low latency and expressive speech generation